
Background
High-performance data compression can alleviate capacity bottlenecks and even improve performance in GPU compute applications, by reducing memory bandwidth requirements. However, integrating compression throughout the entire data processing pipeline is a non-trivial task, especially in multi-GPU environments, and doing so manually tends to bake in assumptions that make it difficult to experiment with different compression methods, particularly domain-specific ones that exploit the structure of a specific kind of data.
The research project UMUGUC set out to make such compression methods easy to use in multi-GPU cluster applications, without requiring application developers to write any compression-specific code, and without requiring compression-algorithm developers to deal with the complexities of distributed execution, data movement, or synchronization.
Make it easy to work with end-to-end compressed (dense) data in multi-GPU programs — including custom, domain-specific compression algorithms.
The project builds on the Celerity runtime system, which provides a high-level C++ programming model for distributed-memory clusters of GPUs. Celerity itself layers on top of the Khronos SYCL standard, ensuring portability across different GPU vendors and architectures.
Overview
UMUGUC's main contribution is a user-facing API design and its implementation, built on top of Celerity's existing buffer/accessor programming model. It has two sides, targeting two different audiences: application developers and compression algorithm developers.
On the application side, a program simply declares a buffer as compressed<...>
and then accesses it exactly like an uncompressed one — no compression-specific code required. On
the
compression-developer side, a small, typed interface lets someone implement a new
compression algorithm, including
domain-specific ones, without having to deal with Celerity's distributed execution, data movement, or
synchronization at all.
As part of this work, we introduced a classification of compression methods into four compression categories, based on where in the GPU memory hierarchy (de)compression happens; this categorization is an integral part of the API design and is illustrated below: element-wise compression of individual values, local-memory and global-memory compression of whole tiles/chunks of data, and traditional, application-level kernel compression using a dedicated compression pass. UMUGUC implements runtime support for the first three of these categories; kernel compression is simply the conventional way of doing things without any special runtime support, requires no additional infrastructure, and is shown below only for context.

On the compression-developer side, algorithms can also declare auxiliary buffers or
per-tile metadata they need
— which is often the case for domain-specific methods. A compression method is expressed as a
wrapper bundling (i) the
numerical compress/decompress logic and (ii) a dependency_bundle describing
any auxiliary buffers it
needs, along with how those buffers should be distributed relative to the compressed data. Given just
this wrapper, Celerity
automatically reserves the compressed and auxiliary buffers, distributes them across GPUs and nodes, and
routes execution to the
right compression code, as seen below.
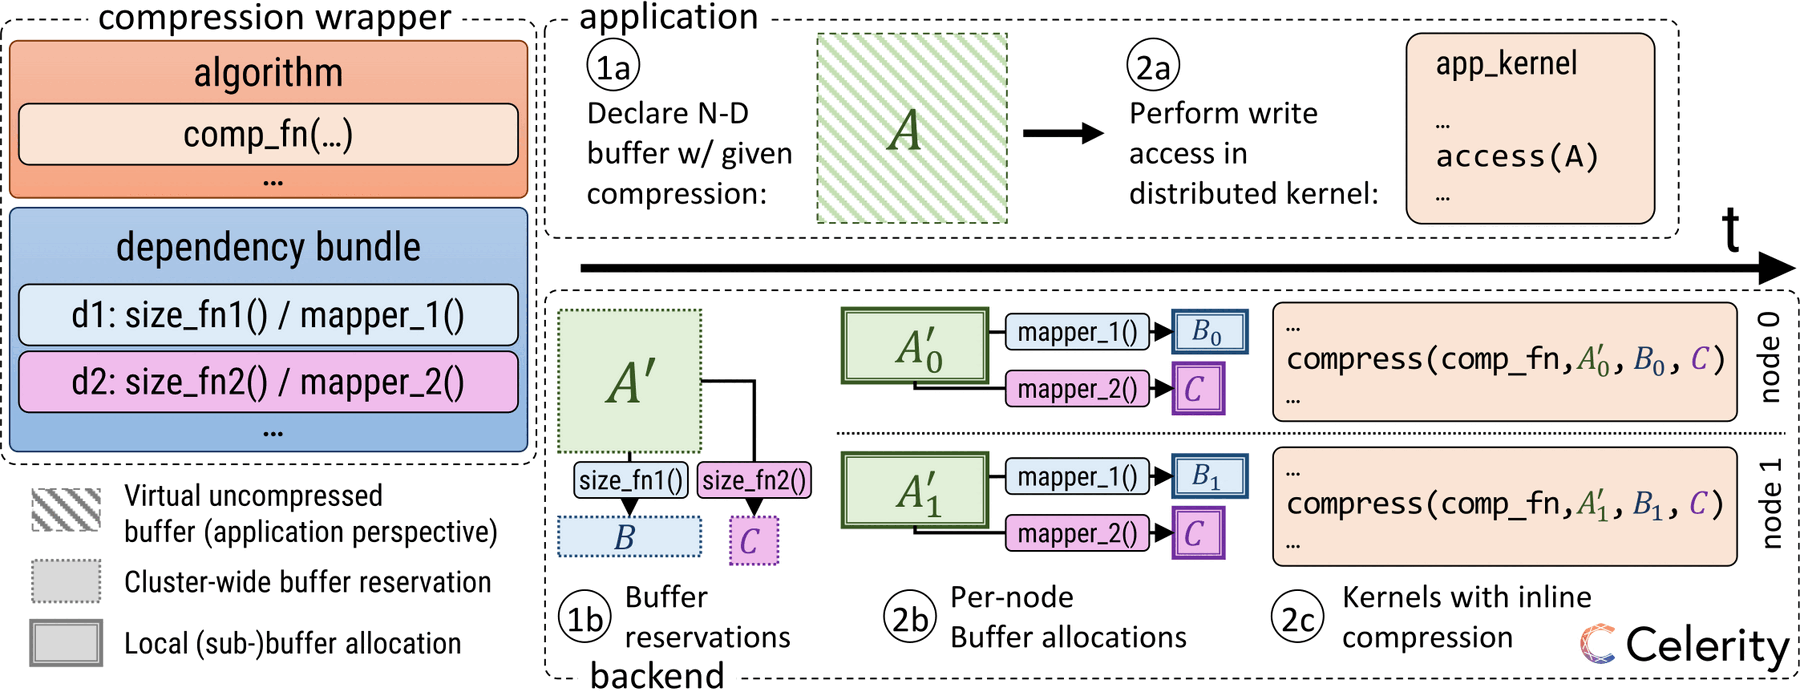
A user-defined compression bundle (left) is used to declare a compressed buffer (top); the runtime then reserves, distributes and populates the compressed buffer together with its auxiliary dependency buffers across GPUs and nodes (bottom).
Example: Z-Curve Point Cloud Compression
As a representative domain-specific algorithm, the project implemented z-curve compression for 3D point clouds, such as those produced by airborne LIDAR scanning. Points are quantized onto a 2D z-curve (a space-filling curve that preserves locality) within each grid cell, so that the X/Y position collapses into a single Morton-encoded index; the remaining Z-offset is stored separately as a half-precision value in an auxiliary dependency buffer.
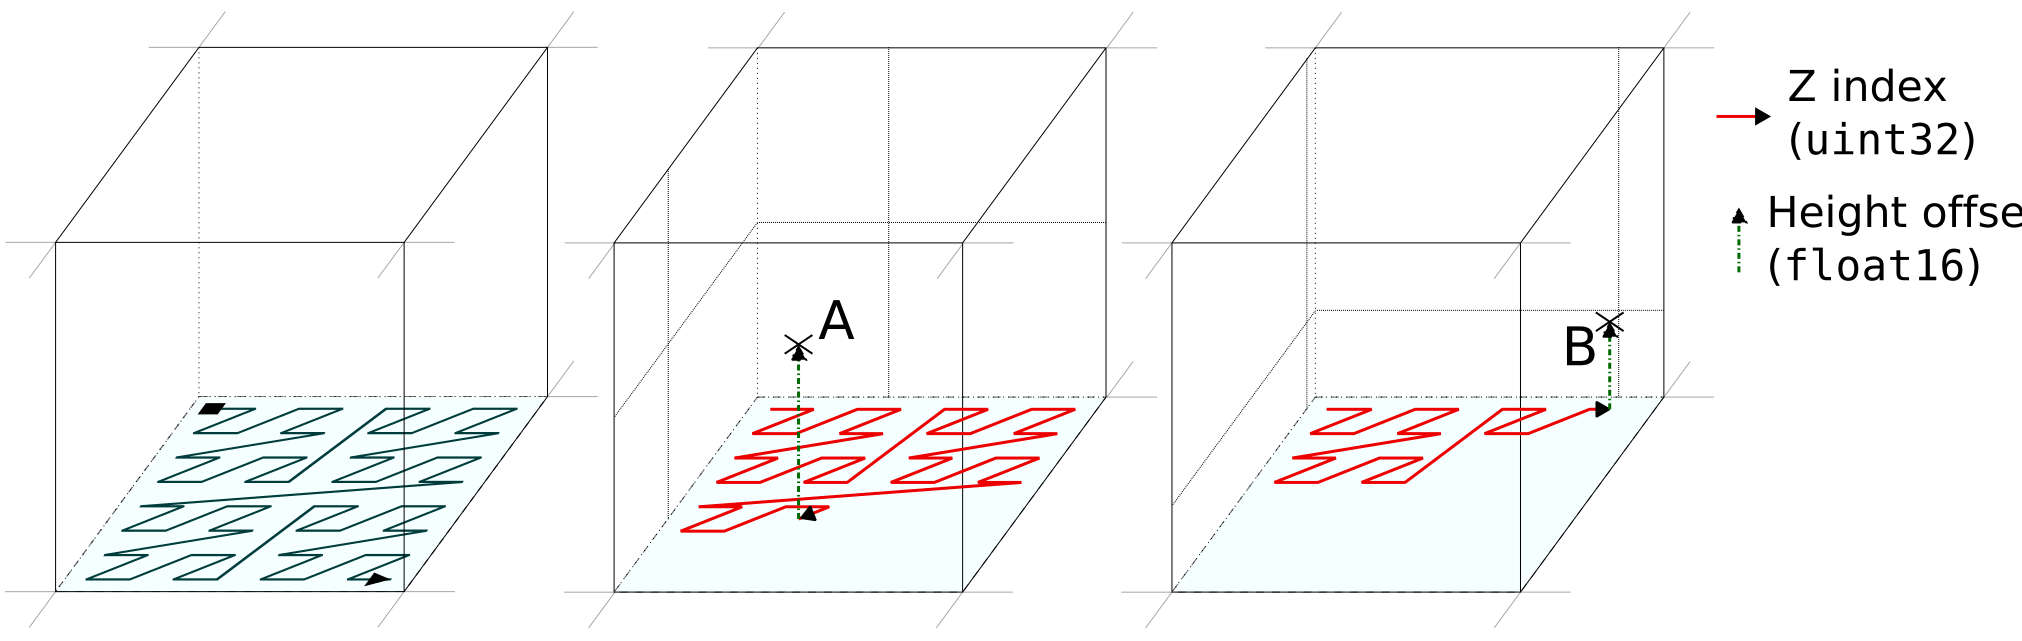
Implementing this — and any other — domain-specific algorithm with the new API only requires two things: a small wrapper exposing the compression object and its dependencies, and the compress/decompress logic itself. Everything else, including allocation, distribution and synchronization of the auxiliary Z-offset buffer, is handled by the runtime:
using compression_t = z_curve_compression<Point, uint32_t, category::local_memory>;
compression_t z_curve{Point{x_min, y_min, 0}, xy_resolution};

// Compressed buffer instead of a regular one - same buffer/accessor API otherwise.
celerity::buffer<Point, 3, compression_t>
    tile_points({width, height, points_per_tile}, z_curve);

queue.submit([&](handler& cgh) {
    accessor tile_point_acc{tile_points, cgh, full_third_dim<3>{}, read_only};
    ... // kernel code accesses tile_point_acc exactly like an uncompressed buffer
});
Evaluation & Scope
The API was evaluated by implementing several element-wise, local-memory and global-memory compression methods — including the z-curve algorithm above and other domain-specific and quantization-based techniques — on three GPU-cluster benchmarks (airborne point cloud processing, a wave simulation, and a room-response simulation) across three different hardware platforms.
The design does have limits: compression logic must be expressible on the GPU, it primarily targets fixed-size (rather than e.g. entropy-coded) compression schemes, and writing a dependency's range mapper still requires understanding the algorithm's access pattern in detail.
Example Result: Point Cloud Pipeline
Of the three benchmarks, the airborne point cloud pipeline is shown here as an example. The figure below compares all compressed variants against the uncompressed baseline on 1, 2 and 4 GPUs.
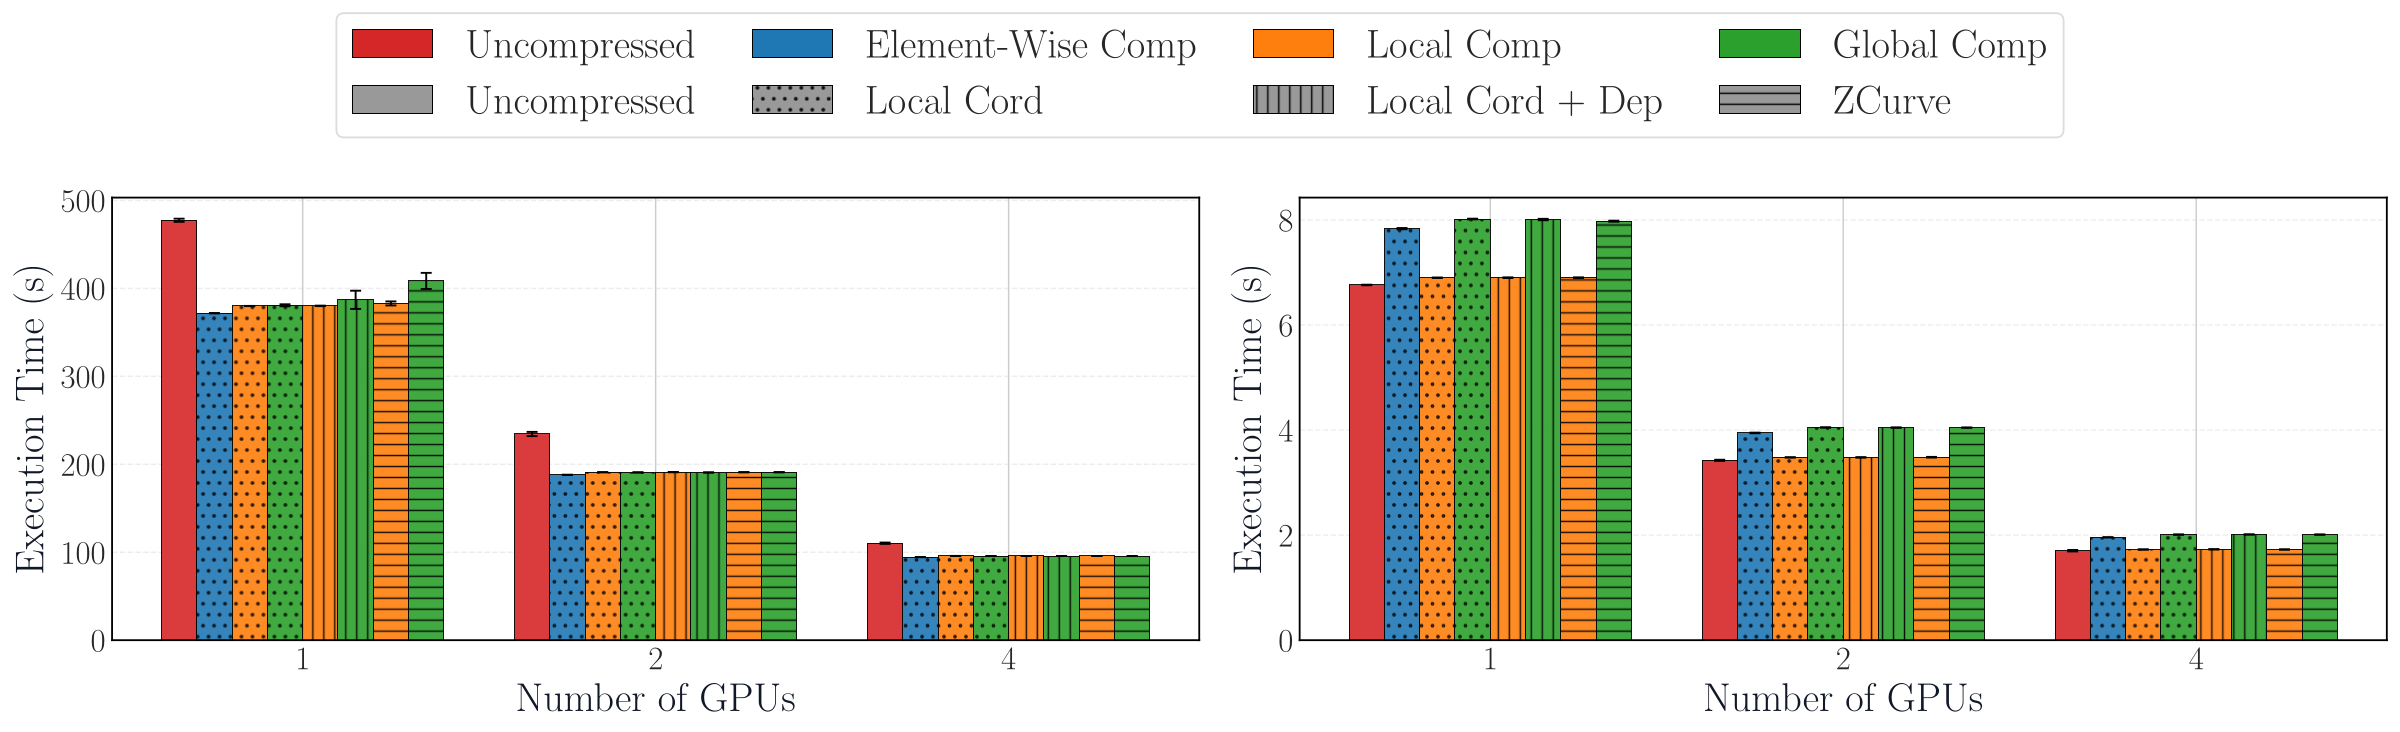
Execution time of the tiling stage (left) and the shape-factor computation (right) for each compression category (color) and algorithm (pattern).
In the tiling stage, which sorts points into spatial tiles, every compressed variant runs around 15–20% faster than the uncompressed version. In the shape-factor stage, which analyses how points are distributed in close proximity, local-memory compression matches the uncompressed version, while the other categories add an overhead of up to about 18%. However, this stage takes only a few seconds compared to hundreds for tiling, so the overhead is negligible and the pipeline as a whole runs faster with compression. All variants scale well across multiple GPUs, without any compression-specific code in the application.
The results for the wave and room-response simulations, the other hardware platforms and the achieved memory savings are presented in the papers and talks listed under Publications & Talks below.
Technology
UMUGUC was built on top of the Celerity runtime system, which provides a high-level programming model for distributed-memory clusters of GPUs. Celerity is built on top of the Khronos SYCL standard, and provides a data-parallel multi-GPU programming model with a single-source C++ interface. The UMUGUC project extended Celerity with the necessary abstractions to support end-to-end, domain-specific data compression.


Celerity Releases During the Project
Alongside the compression work, Celerity itself evolved from version 0.4.0 to 0.7.1 over the course of the project. These releases brought important improvements to the underlying runtime, most of which were essential for the UMUGUC project:
- 2023-12-21 : 0.5.0 — stable fences and buffer snapshots, plus task hints for controlling how work is split.
- 2024-08-12 : 0.6.0 — a single process now drives all GPUs of a node, backed by a new instruction graph for more asynchronous execution.
- 2025-08-18 : 0.7.0 — a new SYCL-style
celerity::queueAPI on C++20, with per-device submission threads for better performance. - 2026-09-02 : 0.7.1 — Windows support.
Tooling
Alongside the API and its evaluation, the project produced a small set of supporting command-line and GUI tools, released separately in the umuguc/tooling repository:
- Data Converter — converts AirborneHydroMapping's HDF5-based airborne LIDAR point clouds into the plain, uncompressed binary point format used by UMUGUC's point cloud benchmark.
- Visualizer — an Open3D-based viewer for interactively inspecting point clouds and the pipeline's intermediate results, including height maps, spatial tile grids, and per-tile shape factors.
Both tools are self-contained CMake projects; see the repository's README for build instructions and usage details.
Publications & Talks
- Talk:
High-level Domain-specific End-to-end Compression in GPU Cluster Runtime Systems
Gabriel Mitterrutzner & Peter Thoman
HLPP'26: 19th International Symposium on High-level Parallel Programming and Applications (2026) - Talk:
Concurrent Scheduling of High-Level Parallel Programs on Multi-GPU Systems (Best Paper Award)
Peter Thoman, Fabian Knorr & Philip Salzmann
HLPP'26: 19th International Symposium on High-level Parallel Programming and Applications (2026) - Journal Paper:
A High-level API for End-to-end Data Compression in Multi-GPU Cluster Applications
Gabriel Mitterrutzner, Peter Thoman & Philipp Gschwandtner
International Journal of Parallel Programming, 54(3) (2026) - Journal Paper:
Bridging Usability and Performance: High-level Abstractions for Advanced Accelerator Cluster Programming
Philip Salzmann, Fabian Knorr, Peter Thoman, Philipp Gschwandtner & Thomas Fahringer
Future Generation Computer Systems, 177 (2026) - Talk:
A High-level API for End-to-end Data Compression in Multi-GPU Cluster Applications
Gabriel Mitterrutzner, Peter Thoman & Philipp Gschwandtner
HLPP'25: 18th International Symposium on High-level Parallel Programming and Applications (2025) - Conference Paper:
Achieving High-throughput Strided Data Movement Across GPUs (Best Paper Award)
Peter Thoman & Philipp Gschwandtner
IWOCL '25: Proceedings of the 13th International Workshop on OpenCL and SYCL (2025) - Talk:
Celerity - SYCL-Based High-Productivity Development at HPC Scale
Peter Thoman
PASC '25: Platform for Advanced Scientific Computing (2025) - Journal Paper:
Celerity-RSim: Porting Light Propagation Simulation to Accelerator Clusters Using a High-Level API
Peter Thoman, Philipp Gschwandtner, Facundo Molina Heredina & Thomas Fahringer
International Journal of Parallel Programming (2025) - Conference Paper:
SimSYCL: A SYCL Implementation Targeting Development, Debugging, Simulation and Conformance
Peter Thoman, Fabian Knorr & Luigi Crisci
IWOCL '24: Proceedings of the 12th International Workshop on OpenCL and SYCL (2024)
Partners & Funding
UMUGUC was funded by the Austrian Research Promotion Agency (FFG) under the BRIDGE programme, running from September 2023 to August 2026.
The project partners were the University of Innsbruck, and AirborneHydroMapping GmbH.
UMUGUC was coordinated by Peter Thoman.

